Every AI agent that reads the web first turns HTML into text. extract-bench tests six open-source tools for that step on pages where the right answer is known, with a 95% bootstrap interval on every number and a label for every failure.
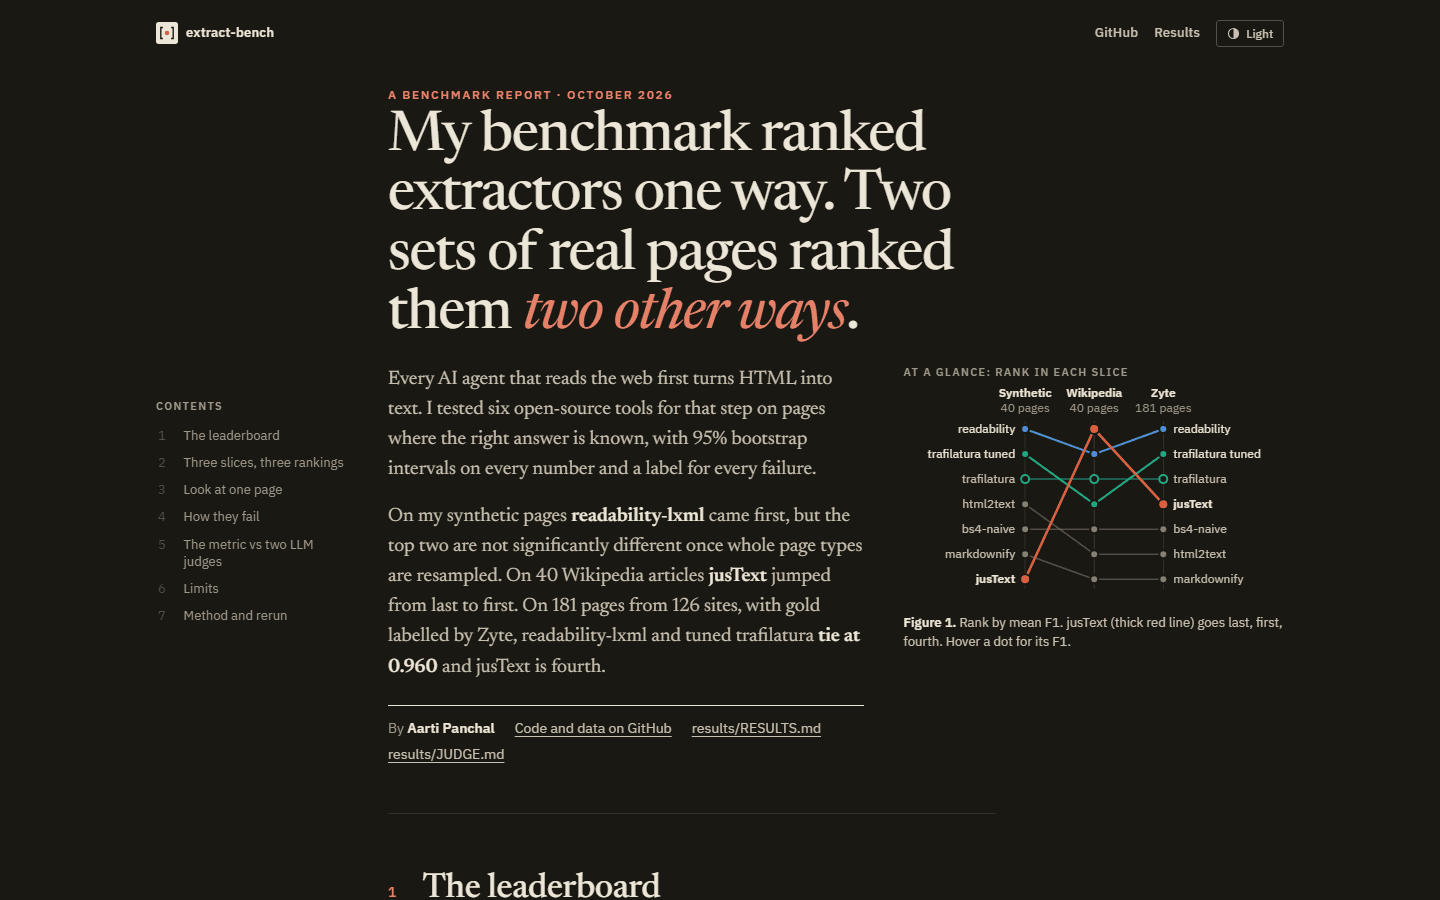
The interesting part is that the ranking did not survive contact with real pages. On my synthetic pages readability-lxml came first. On 40 Wikipedia articles jusText jumped from last to first. On 181 pages from 126 sites, labelled by people at Zyte, readability-lxml and tuned trafilatura tie at 0.960 and jusText is fourth.
I also measured an LLM judge against the metric: two models graded 140 outputs, and the best agreed with the metric at Cohen's kappa 0.74. Both judges flagged the same cases where the metric was too lenient.
Stack used
What I learned
- •Designing a benchmark with known gold, a dev/test split and confidence intervals, instead of one average
- •Checking my own result against outside data and reporting it when it changed
- •Validating an LLM-as-judge against a metric before trusting either